Ideas made tangible.
| Project | Year | Domain | Key fact | Stack | |
|---|---|---|---|---|---|
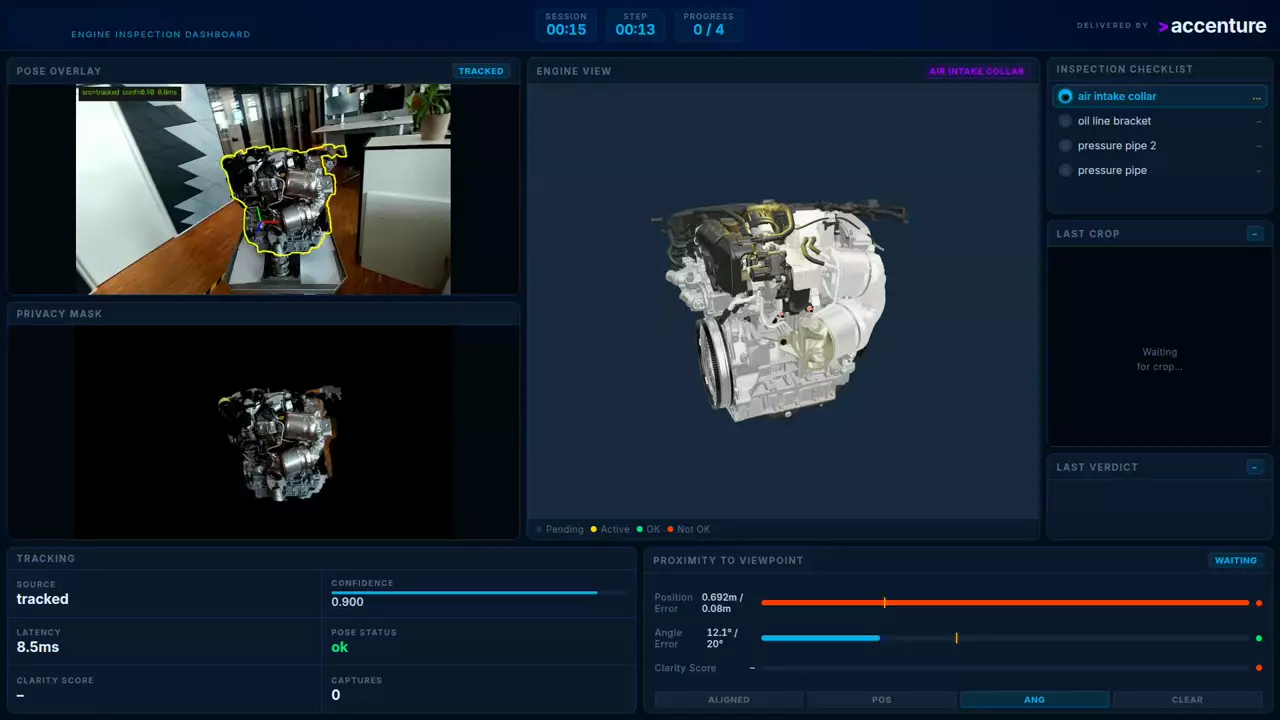 | AR-guided OEM parts inspectionRGB-only 6-DoF engine tracking on AR glasses guides a parts checkRead the story | 2026 | 6D pose estimation | 3.45×LightSpeedGlue speedup |
|
 | Lab of the FutureAn AMR and a UR5e run sample tubes through lab instrumentsRead the story | 2026 | manipulation | 0 humansin the loop |
|
 | Underbody unscrewingMobile robot unscrews car underbodies; YOLOv8 + one-shot calibrationRead the story | 2026 | manipulation | < 1 mmend-to-end error |
|
 | LLM-powered cobot manipulationSpeak to it; it finds, poses and grasps any CAD-onboarded objectRead the story | 2025 | manipulation | 3 armsone robot interface |
|
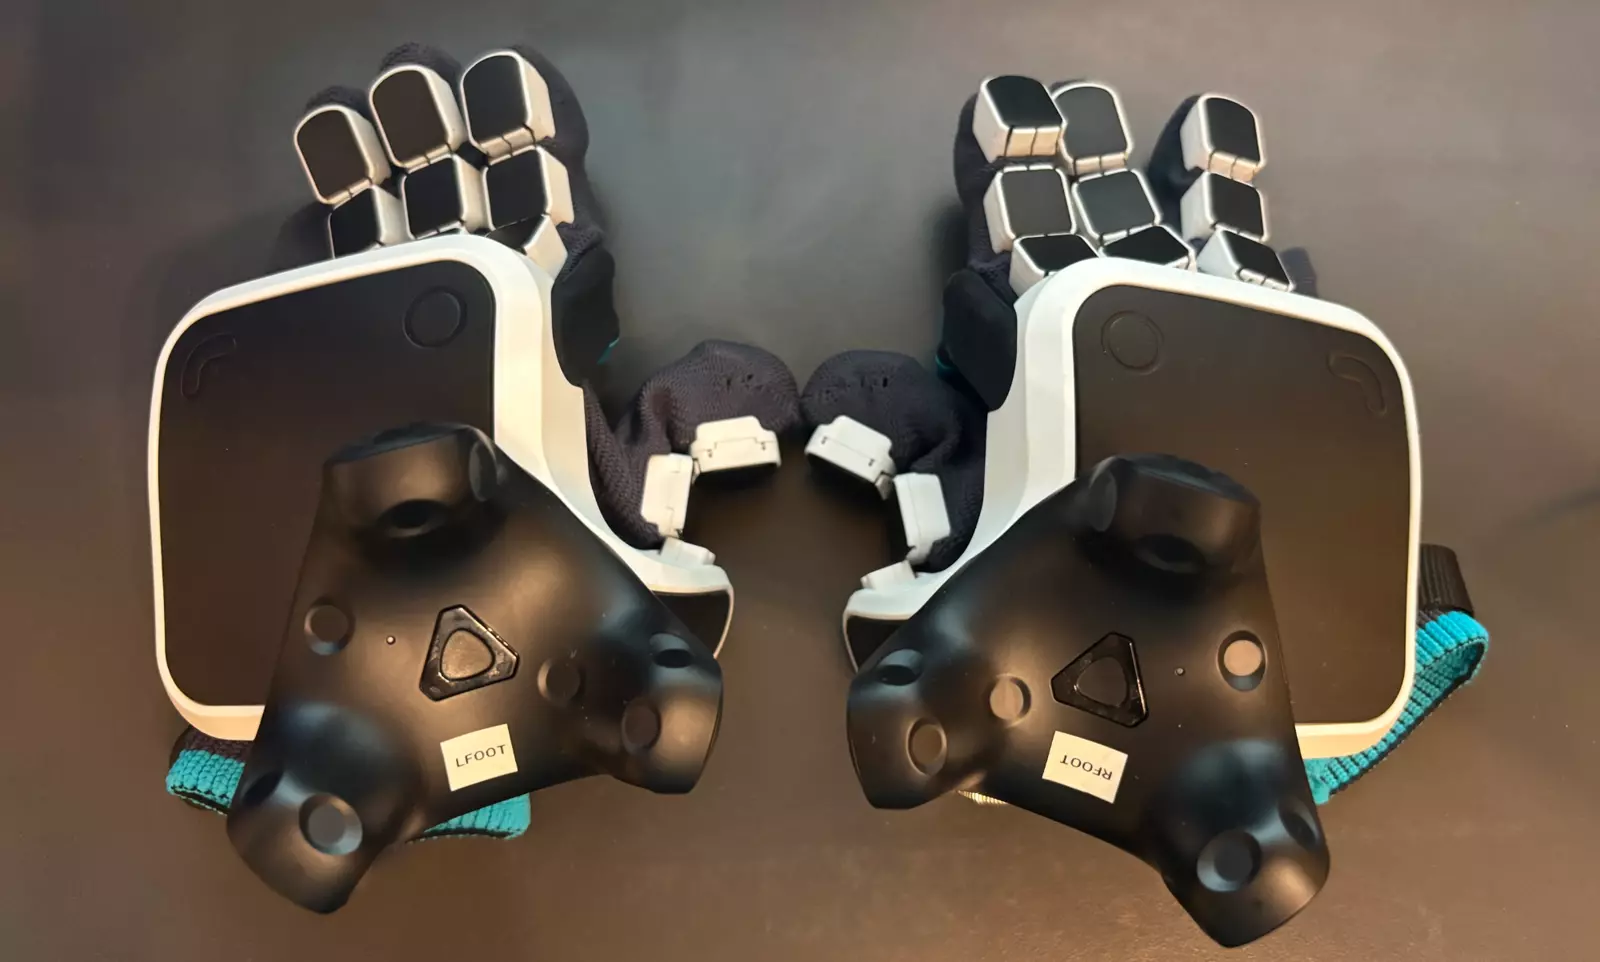 | Humanoid teleoperationGloves and trackers drive humanoid arms and hands. No headset.Read the story | 2025 | teleoperation | 100 Hz+sensor stream |
|
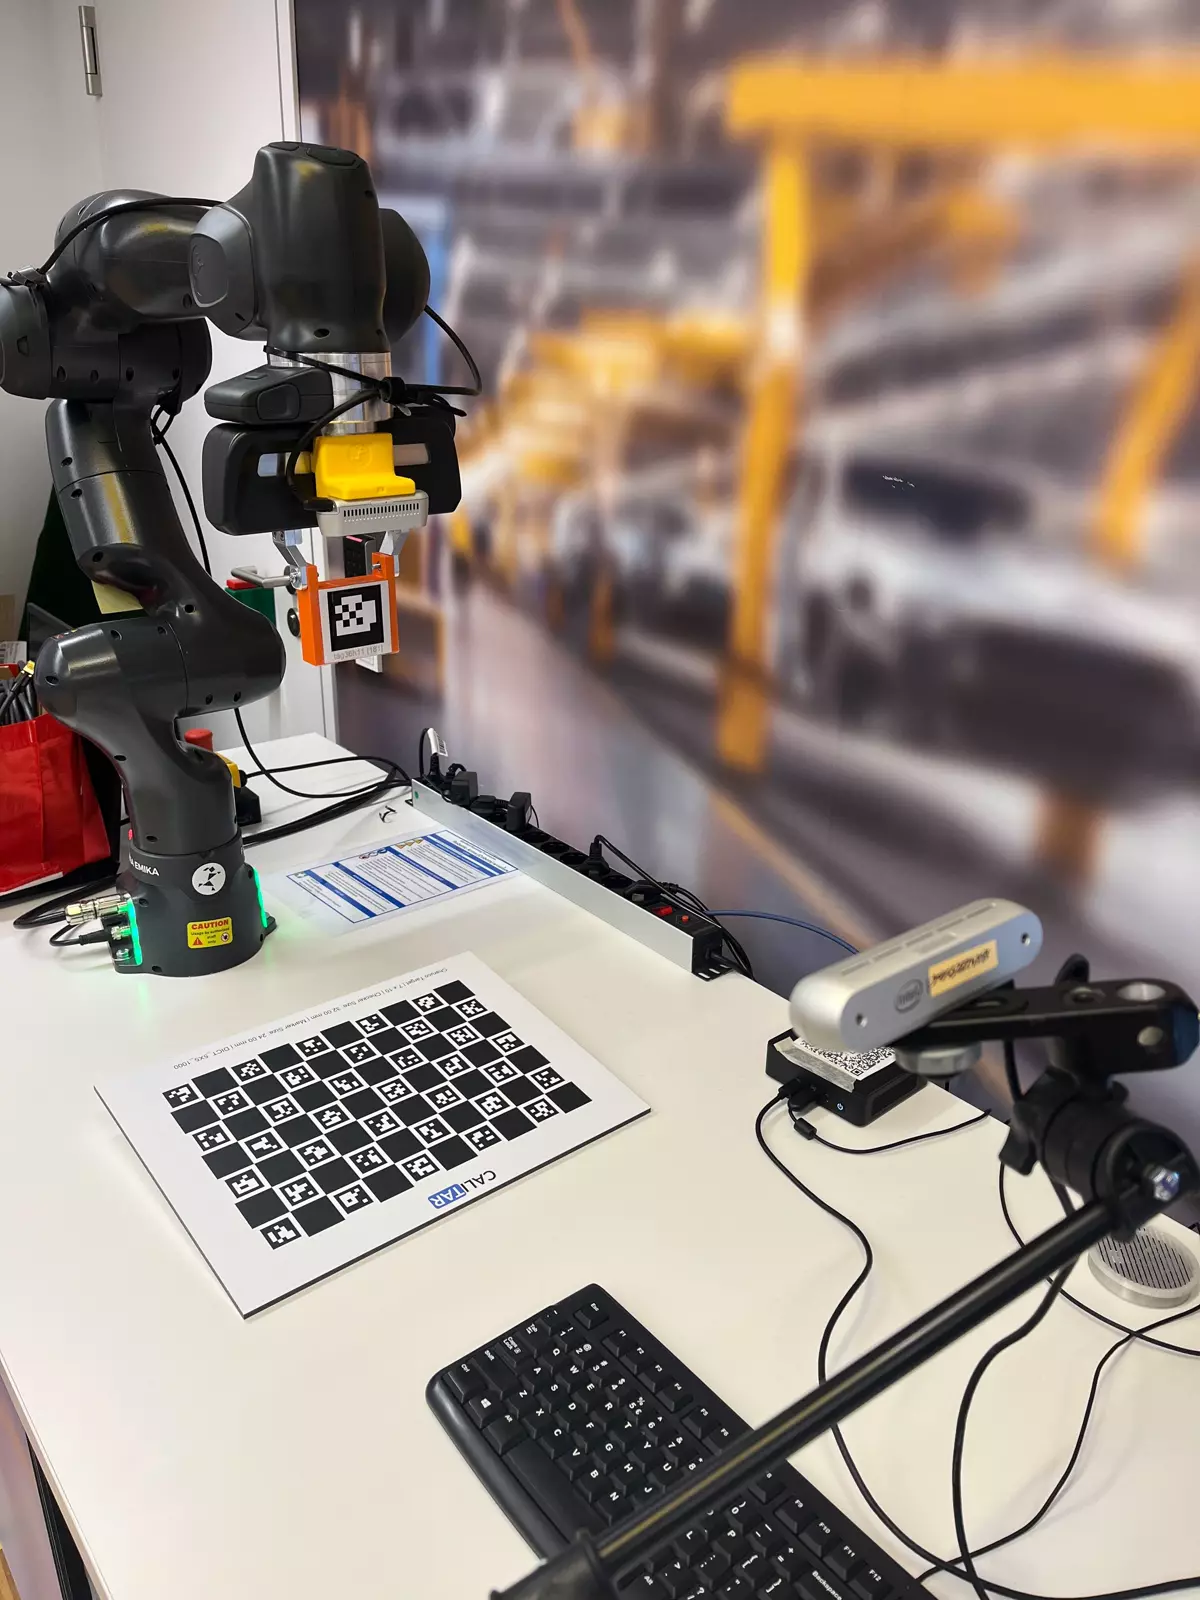 | Hand-eye calibration, three waysBoard, fixed camera, or known geometry. Measured, not assumed.Read the story | 2025 | manipulation | 0.03 mmown solver vs OpenCV |
|
 | Sim-to-real RL ball pushing on a FrankaMy RL policy, trained only in Isaac Lab (Orbit), ran on the real robotOpen link | 2024 | reinforcement learning | 0real-robot training |
|
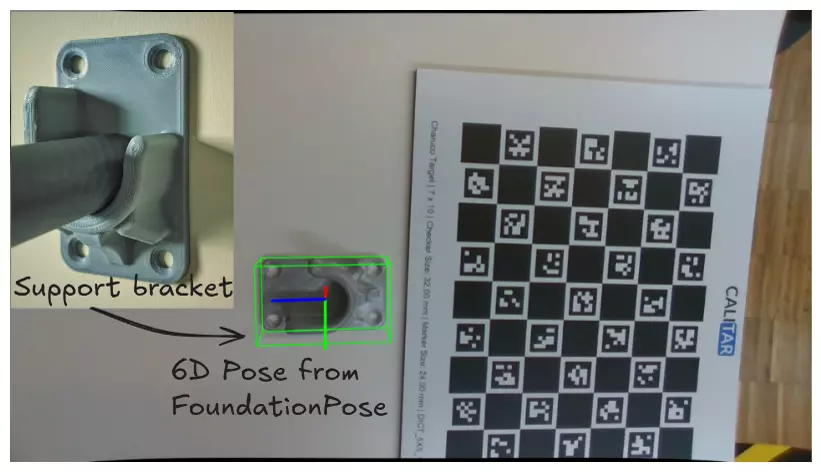 | FoundationPose, measuredRobot scans, a ChArUco world frame and HouseCat6D. When to trust it.Read the story | 2024 | 6D pose estimation | 2.31 mmmean pose error, Zivid |
|
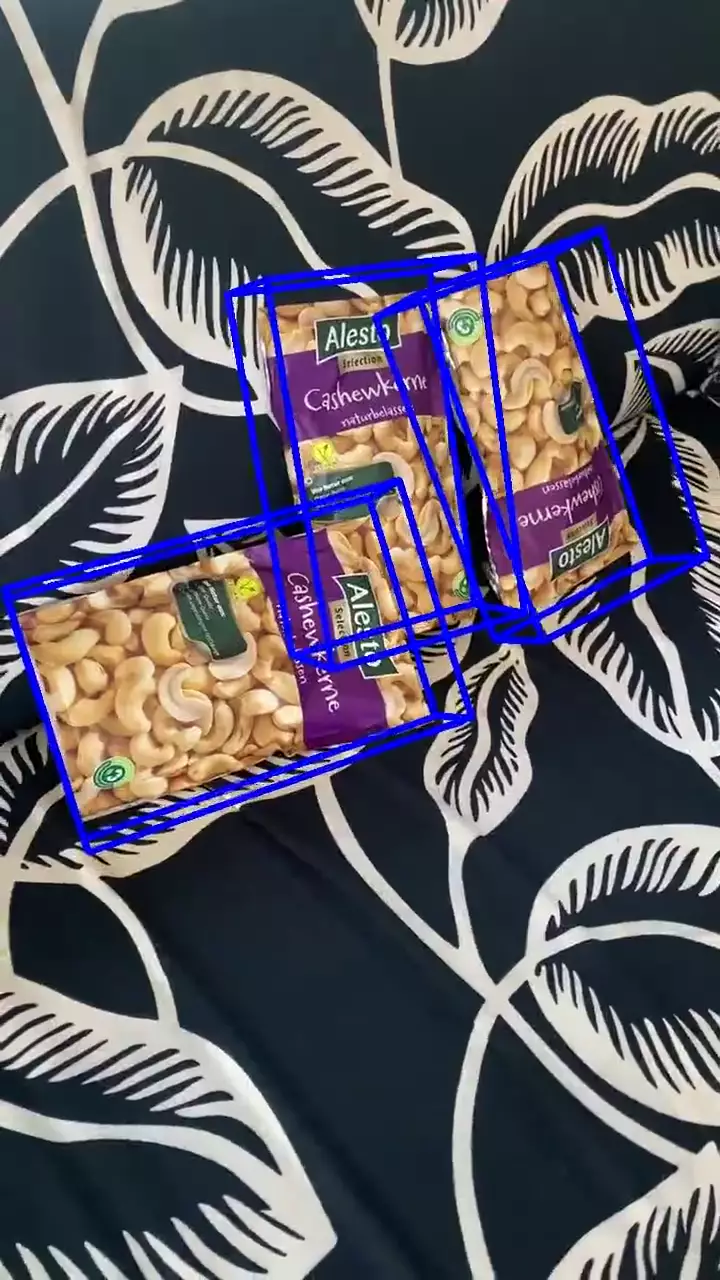 | Training-free 6D pose (OnePose++)Scan on an ArUco board, pose from dense matches. Then fix rotation.Read the story | 2023 | 6D pose estimation | 45°LoFTR rotation limit |
|
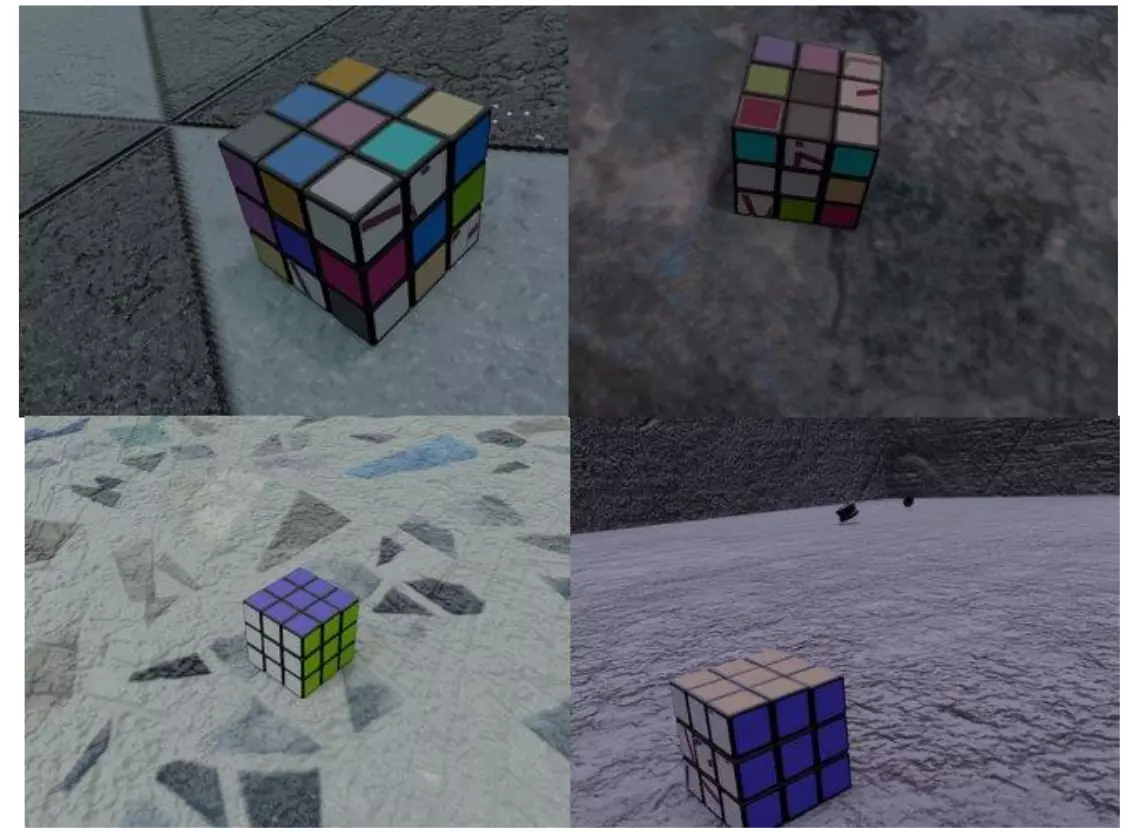 | 6D pose from synthetic-only dataKeypoints + PnP for a cube and a gripper, trained on Blender rendersRead the story | 2022 | 6D pose estimation | GroupNormreplaced BatchNorm |
|
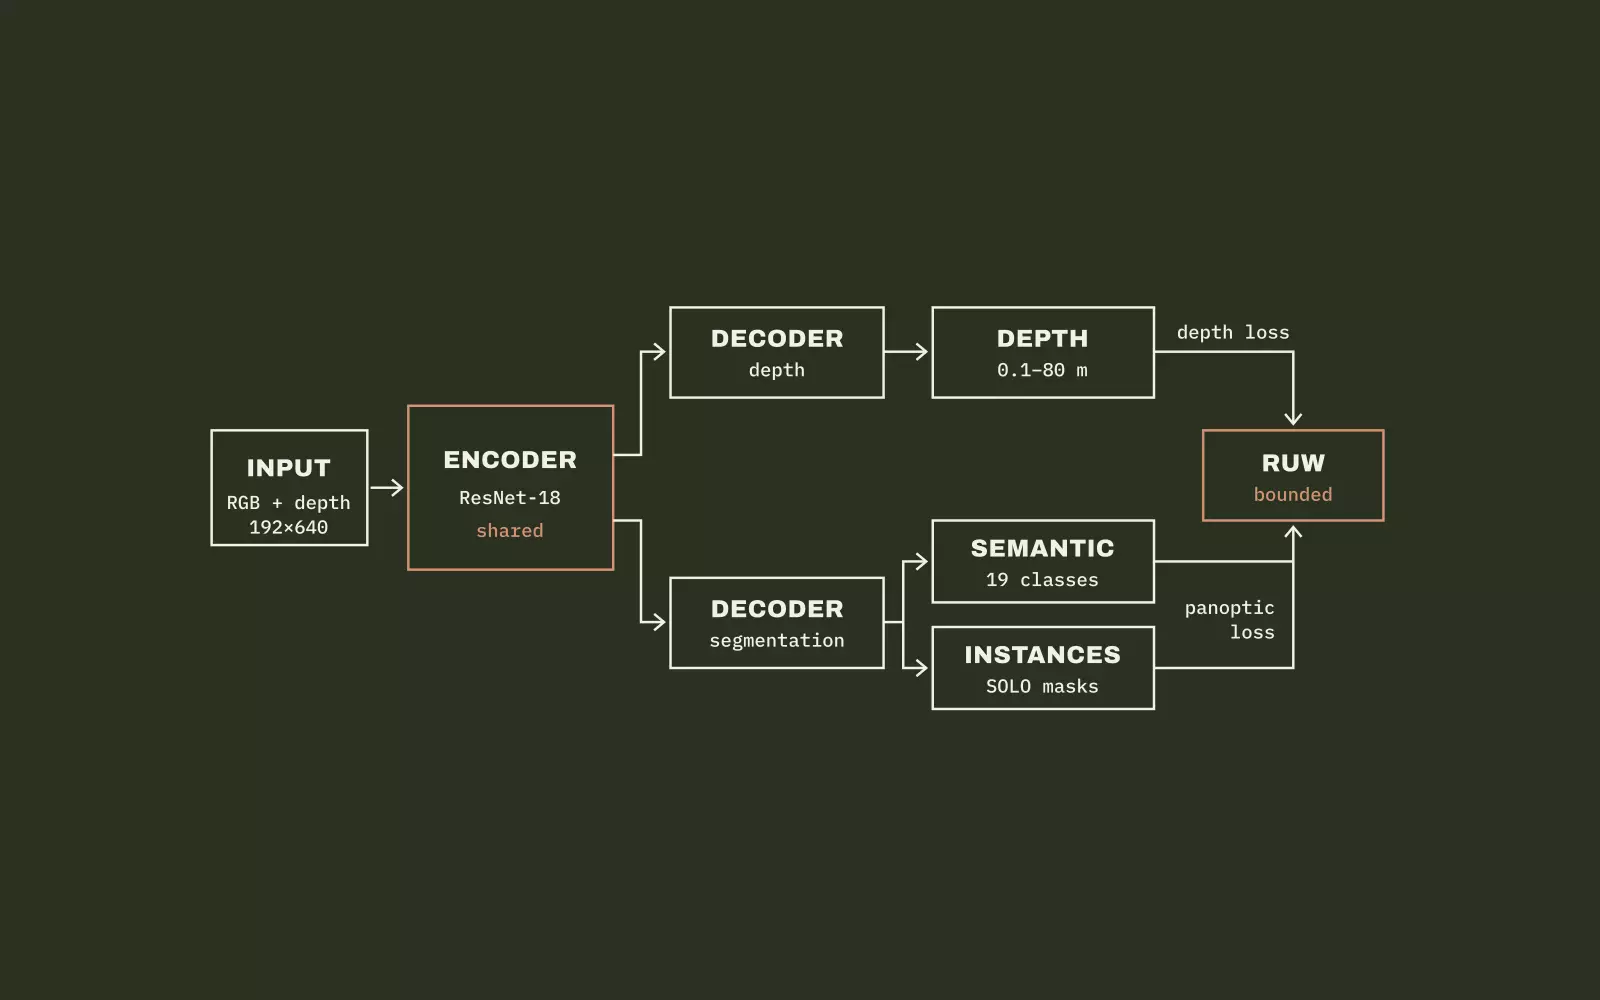 | Perception trilogy: one encoder, 3 tasksShared ResNet-18 encoder, losses balanced by bounded learned weightsRead the story | 2022 | automotive perception | 3 → 1networks, better depth |
|
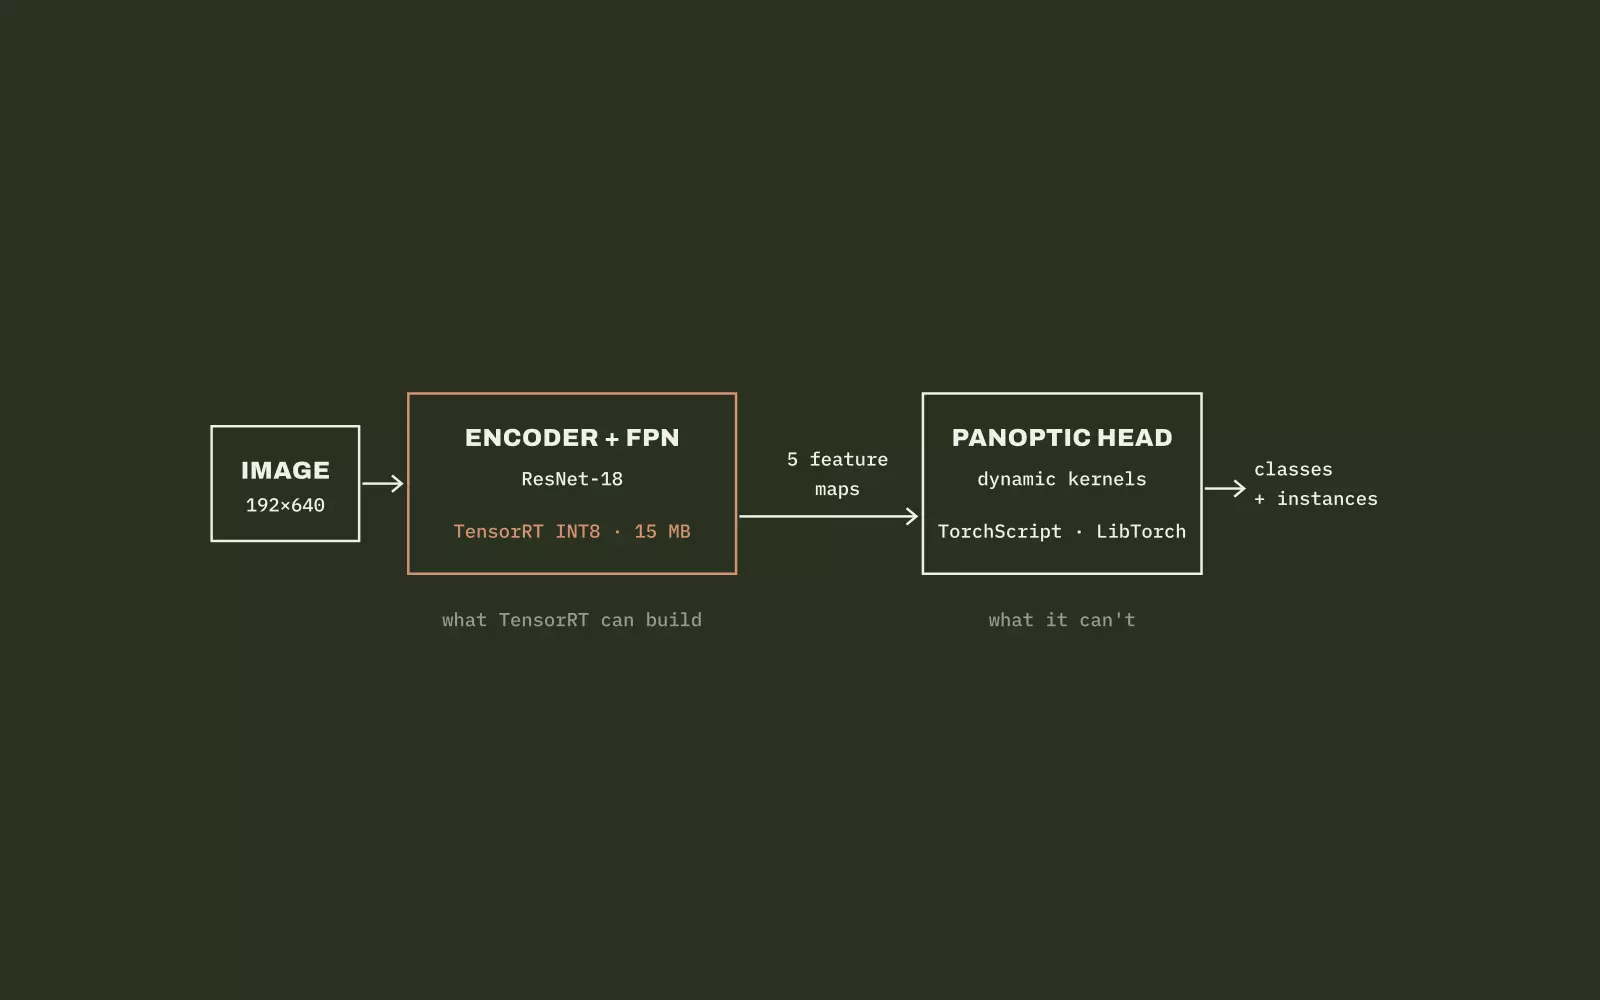 | Panoptic segmentation on embedded hardwareMask R-CNN, SOLO, Panoptic FCN: INT8 encoder + TorchScript headRead the story | 2021 | automotive perception | 15 MBINT8 encoder on AGX |
|
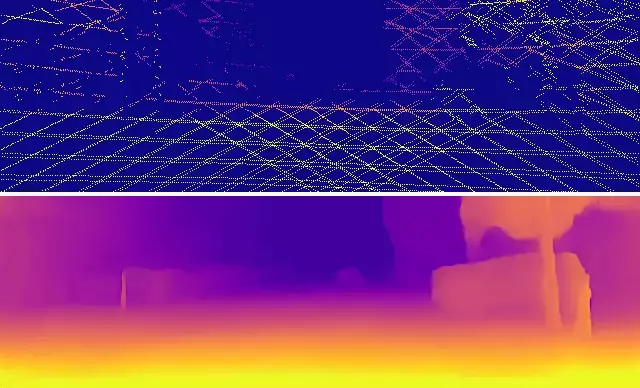 | Real-time depth completionMono depth + a sparse depth channel: metric, cheap, ran in the carRead the story | 2021 | automotive perception | 1 layerends mono uncertainty |
|
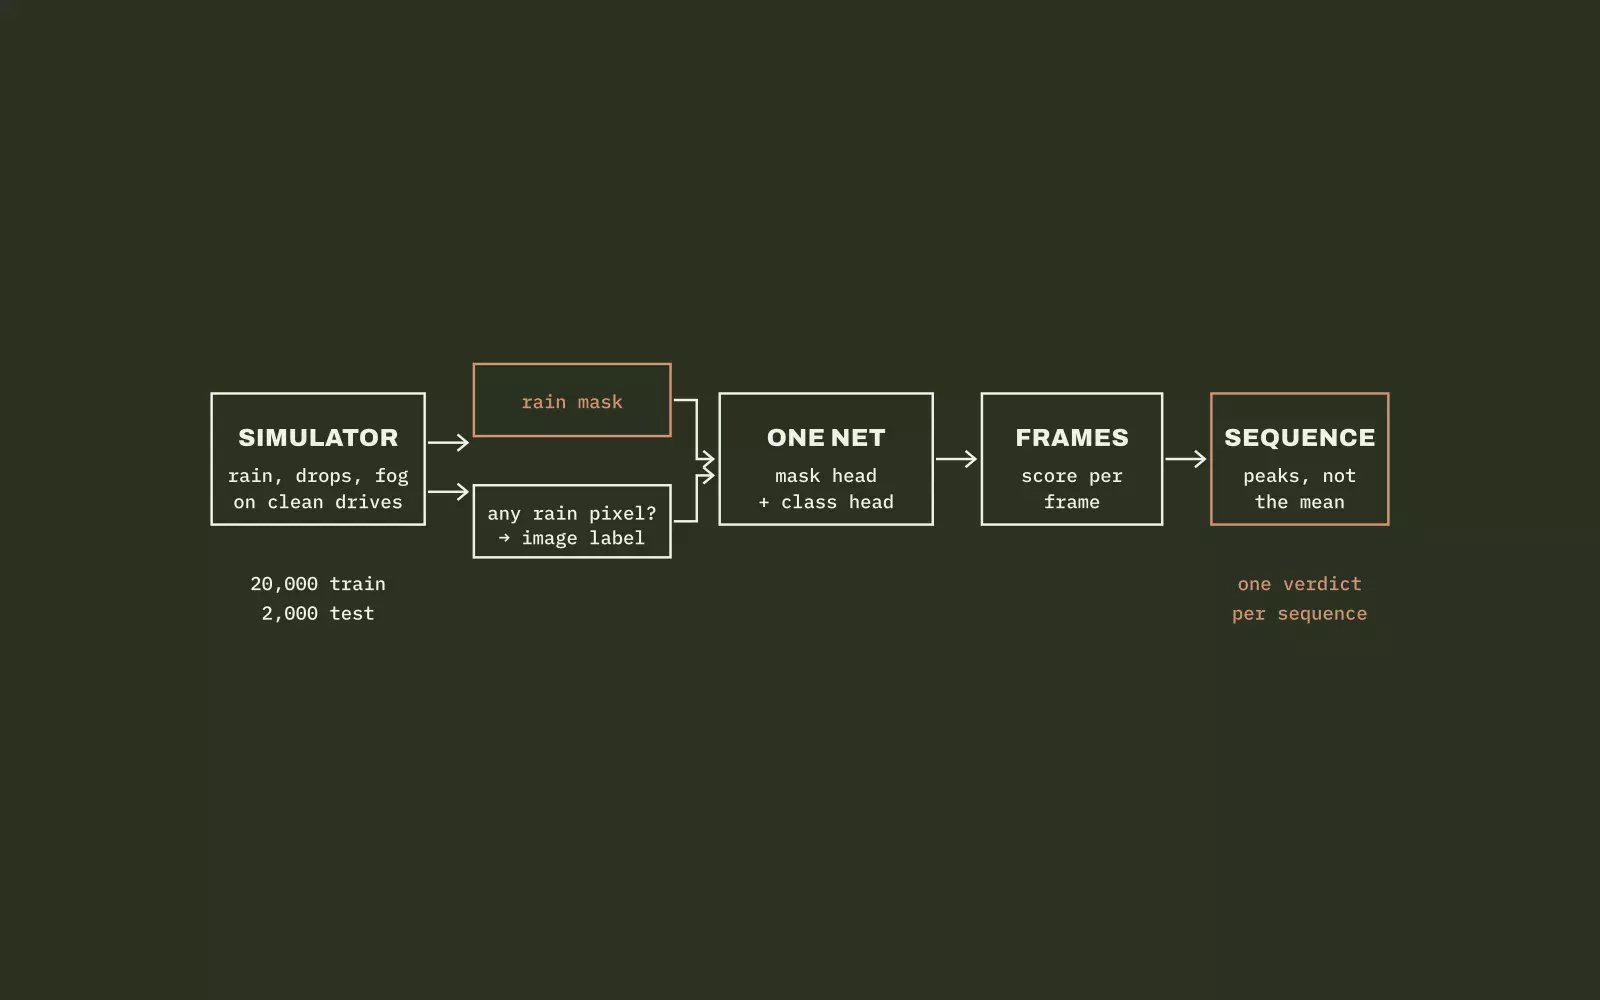 | Rain detection for camera blindnessSimulated rain masks, one net, a sequence rule that beats the wiperRead the story | 2019 | automotive perception | 22,000synthetic rain images |
|
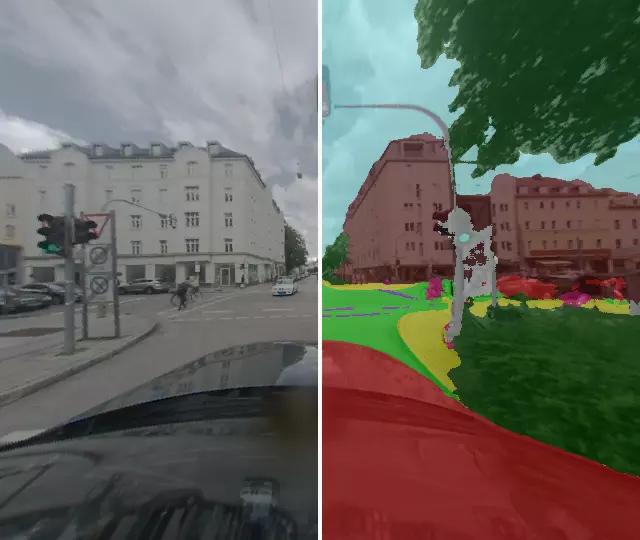 | Real-time segmentation for carsOwn fast nets to INT8 TensorRT engines on Drive PX and AGX, 2017–2021Read the story | 2018 | automotive perception | 0.0 mIoUlost to quantisation |
|
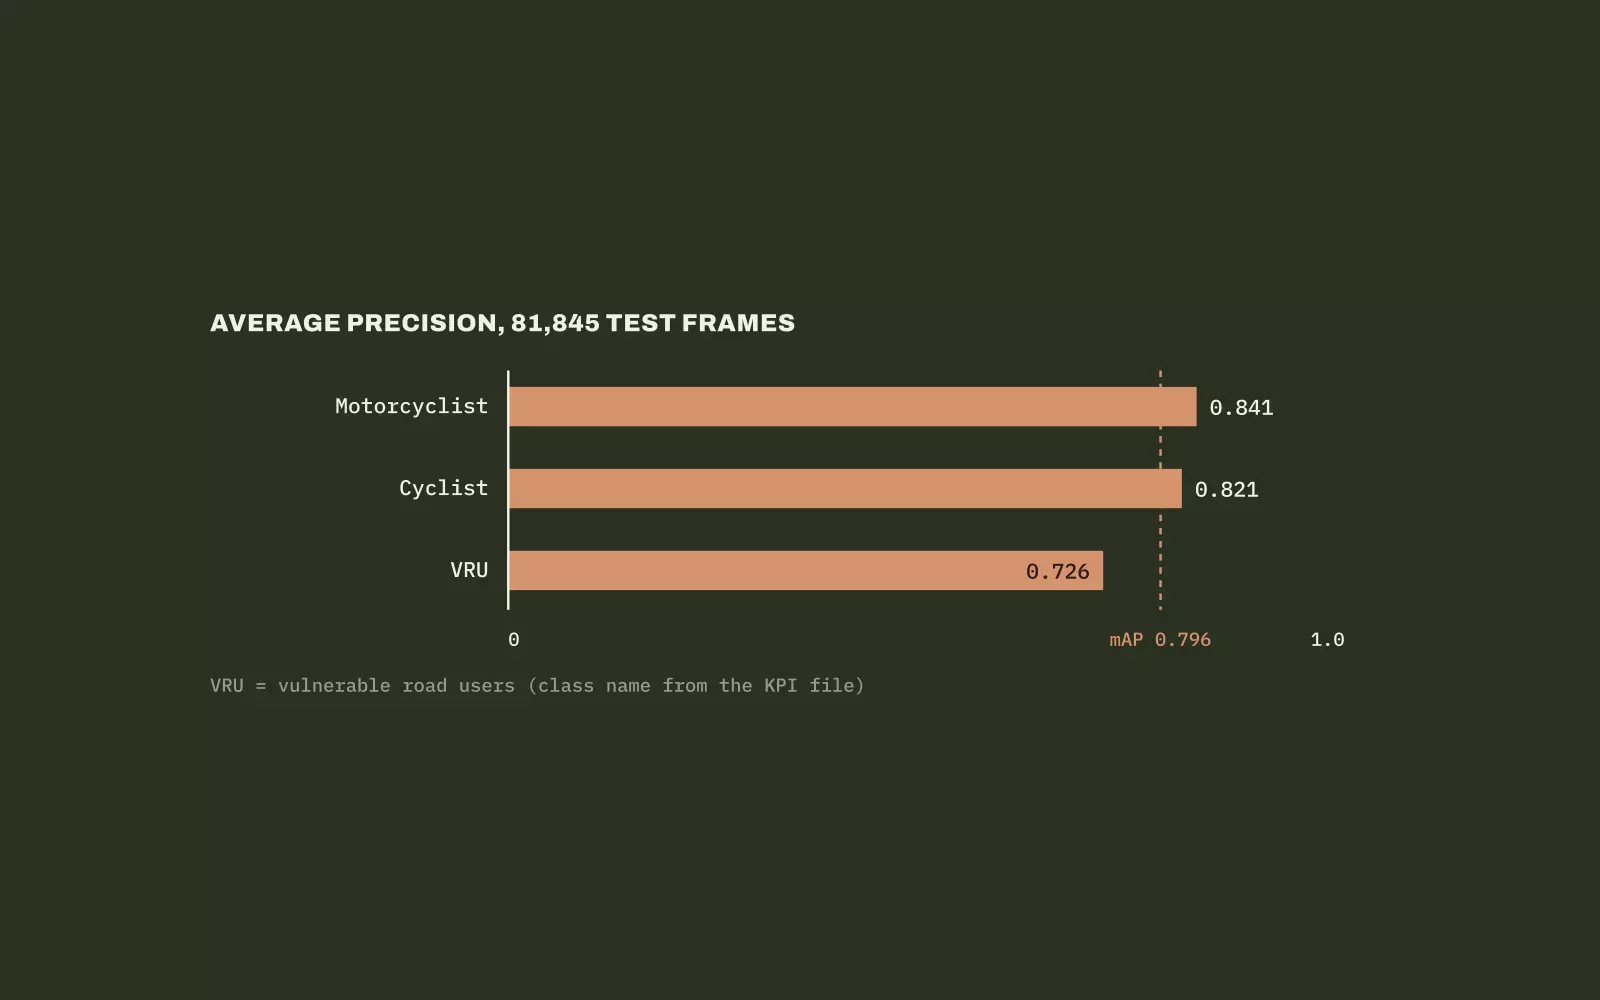 | Video object detection and trackingFlow-guided detection and a Deep SORT tracker for road usersRead the story | 2018 | automotive perception | 0.796 mAP3 road-user types |
|
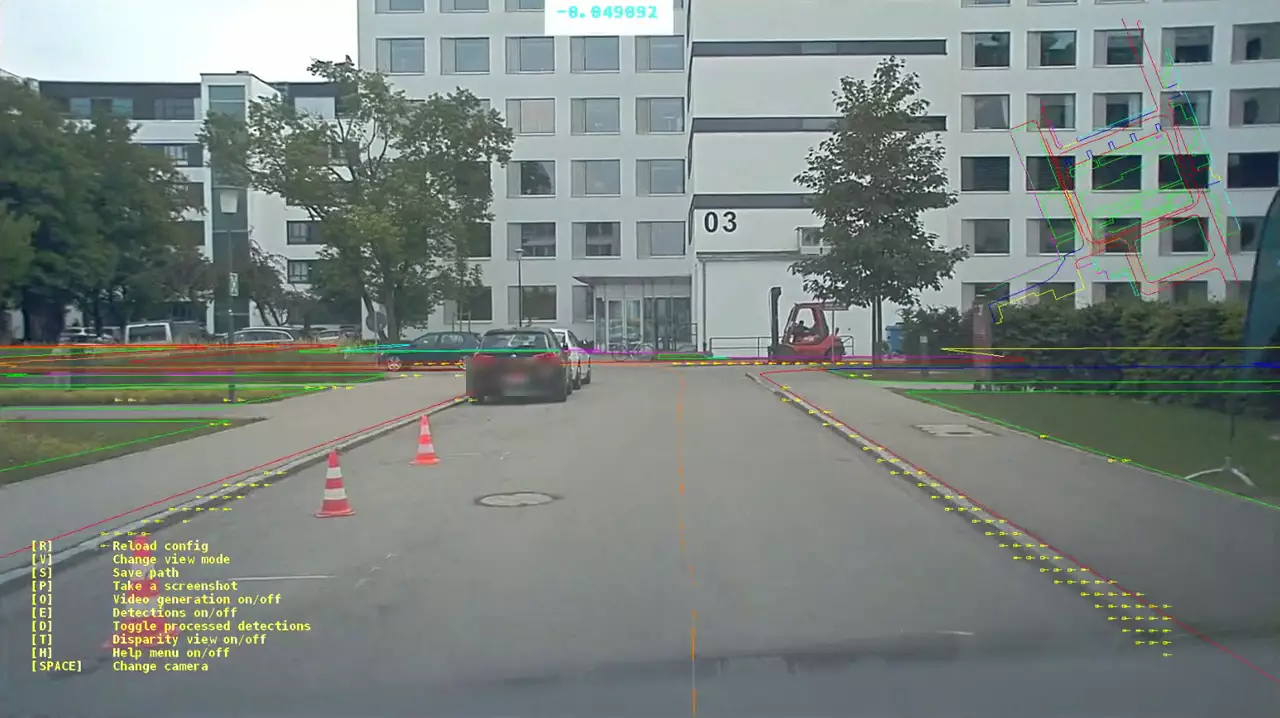 | Camera localisation on Drive PXA debugger traced a corner miss to car tilt; the IMU fixed itRead the story | 2018 | automotive perception | 1 weekto build the debugger |
|
Open source
github.com/krishna-esrlabs ↗My repo
LightSpeedGlue
LightGlue on TensorRT for matching a fixed template against live video. I split it into a template engine that runs once and a per-frame matcher, and got FP16 engines that stay correct by pinning the sensitive ops to FP32.
5.2× faster- Pull request to NVIDIAisaac_ros_object_detection
Change the RT-DETR confidence threshold at runtime, without restarting the node.
- My repotao-rtdetr-isaacros
Fine-tune RT-DETR with NVIDIA TAO on your own data and export a TensorRT engine with the outputs Isaac ROS expects.
- Forkcnos
MobileSAM and SAM2 as segmenters for CAD-based novel object detection, plus a mesh-diameter fix.
- Forkse2-LoFTR
A rotation-equivariant ResNet backbone and 8-rotation training configs, behind the rotation fix in my OnePose++ work.